Quantix
Choosing the right custom GPU server builder can shape an entire AI infrastructure project. Global buyers need more than attractive specifications and fast quotations. They need reliable engineering, transparent communication, and evidence from real deployments.
A capable builder should understand GPU selection, server architecture, power delivery, cooling, networking, and storage. These details matter in a crowded data center. A four-GPU system may require stronger airflow than expected. High-density configurations can also expose weaknesses in rack power planning. Small oversights become expensive later.
Experience should be visible in practical documentation. Look for thermal test results, component compatibility records, burn-in procedures, and clear warranty terms. Ask how the builder handles firmware updates, replacement parts, and remote troubleshooting. These answers reveal more than marketing language.
Not every supplier is equally suitable. Some offer flexible chassis designs but limited international support. Others provide strong technical advice but slower production schedules. That trade-off deserves honest discussion. Perfection is unlikely.
A trustworthy partner should also explain certifications, shipping responsibilities, and regional service limitations. Requirements can differ between Europe, North America, Asia, and other markets. Buyers should verify local electrical and import obligations independently.
This guide examines what makes a top China custom GPU server builder valuable for global buyers. It focuses on engineering depth, manufacturing consistency, communication quality, and long-term support. Real confidence comes from measurable processes, not impressive promises. Even experienced teams can miss details, so careful validation remains essential before large-scale deployment.
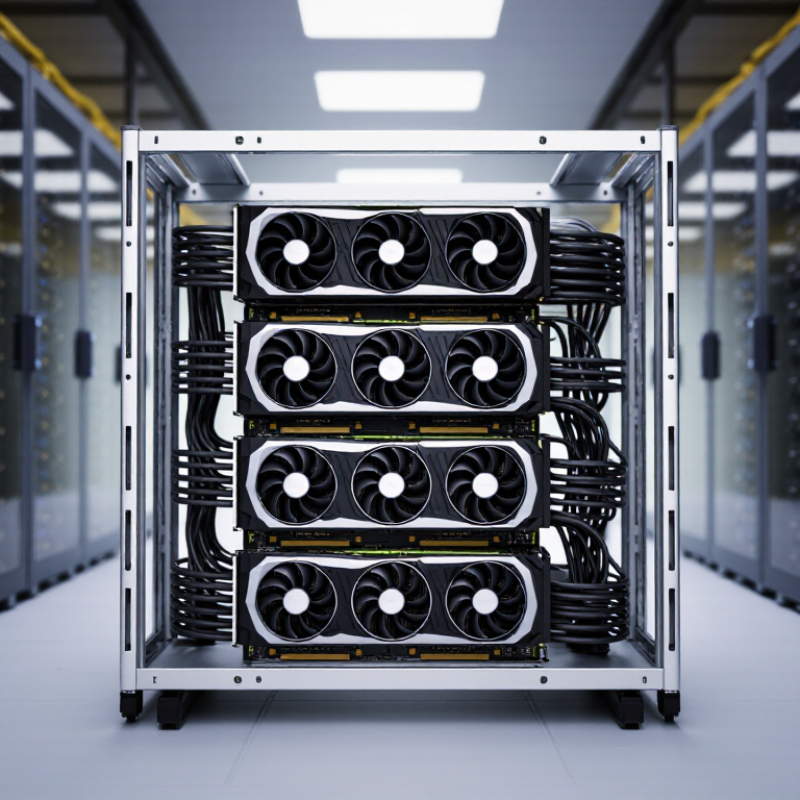
For global buyers, a top China custom GPU server builder is defined by engineering evidence, not low quotations. IDC projected worldwide AI infrastructure spending at $154 billion in 2024, up 44% year over year. That growth increases pressure on power delivery, cooling, and deployment speed. A capable builder should translate workload requirements into GPU density, CPU balance, memory bandwidth, storage paths, and network topology. The proposal should include measured benchmarks, component traceability, firmware records, and a clear burn-in procedure. Proof matters. Not promises.
Thermal design deserves equal attention. Uptime Institute’s 2024 Global Data Center Survey reported an average annualized PUE of 1.58, showing that facility efficiency still varies widely. A serious supplier provides rack-level power budgets, inlet-temperature limits, airflow maps, acoustic readings, and failure-recovery tests. It should also explain when air cooling becomes insufficient and whether liquid cooling is practical for the buyer’s site. International reliability requires more than shipping. Buyers need documented quality controls, serial-level inspection, spare-parts planning, remote diagnostics, and support across time zones. Independent acceptance testing is valuable, especially for multi-node clusters. Yet no builder gets every design right. A mature team records failed tests, revises thermal assumptions, and states limitations plainly. That imperfect honesty can be more reliable than polished sales language.
| Evaluation Dimension | Objective Reference or Benchmark | What a Top Builder Should Demonstrate | Buyer Verification Method |
|---|---|---|---|
| GPU Configuration Flexibility | Support for single-GPU, multi-GPU, PCIe-based, and passively cooled data-center GPU configurations. | Provides configurable chassis layouts, riser options, GPU spacing, auxiliary power, and airflow paths without relying on one fixed design. | Request a mechanical layout, GPU compatibility matrix, thermal design power limits, and a complete bill of materials. |
| PCI Express Capability | PCI Express 4.0 provides 16 GT/s per lane; PCI Express 5.0 provides 32 GT/s per lane. A x16 link uses sixteen lanes. | Correctly matches CPU, motherboard, risers, switches, and GPUs to the required PCIe generation and lane allocation. | Review motherboard block diagrams and validate link speed and width with operating-system hardware diagnostics. |
| GPU Interconnect and Scaling | Multi-GPU workloads may require high-bandwidth peer-to-peer communication in addition to ordinary PCIe traffic. | Offers an application-specific topology for AI training, inference, rendering, simulation, or virtualized workloads instead of treating every GPU workload identically. | Ask for topology diagrams, peer-to-peer test results, collective-communication results, and workload-specific acceptance criteria. |
| Thermal Management | High-performance accelerators can produce several hundred watts of heat per device; total system heat rises with GPU, CPU, memory, and storage load. | Uses validated airflow design, adequate fan redundancy, temperature monitoring, and a defined operating-temperature range. | Require full-load thermal test logs, inlet and outlet temperature data, fan curves, acoustic data where relevant, and GPU throttling records. |
| Power Delivery | A multi-GPU server may require a power supply capacity above 2 kW, depending on GPU, CPU, memory, storage, and workload selection. | Calculates peak and sustained power, supports suitable input voltage, provides redundant PSU options, and leaves practical headroom for transient loads. | Request a power budget, PSU efficiency data, input-current calculations, redundancy mode, and measured stress-test consumption. |
| Memory and Storage Design | Modern GPU servers may require high-capacity ECC system memory, multiple NVMe drives, and separate operating-system, cache, and data storage tiers. | Balances memory channels, capacity, storage endurance, RAID or software-defined storage requirements, and serviceability. | Check the memory population plan, ECC support, NVMe backplane details, drive endurance ratings, and storage replacement procedure. |
| Network Connectivity | Data-center deployments commonly use 10, 25, 40, 100, 200, or 400 Gb/s Ethernet or other high-speed interconnects, depending on workload and infrastructure. | Integrates the required network adapters, PCIe lanes, optics or cables, firmware, and topology without creating a bus bottleneck. | Request port-speed validation, adapter compatibility, cable or transceiver specifications, and sustained network throughput results. |
| Firmware and Software Readiness | GPU workloads depend on coordinated BIOS, baseboard-management-controller firmware, operating-system drivers, runtime libraries, and container support. | Delivers a documented software image, version-control process, recovery method, and reproducible installation procedure. | Request a firmware matrix, driver versions, secure-boot options, image checksum, and a clean-node deployment guide. |
| Validation and Burn-In Testing | A meaningful acceptance test should combine GPU, CPU, memory, storage, network, thermal, and power stress rather than testing isolated components only. | Provides serial-number-linked test records, failure thresholds, test duration, environmental conditions, and corrective-action procedures. | Include burn-in logs, error reports, performance baselines, thermal graphs, and customer-defined factory-acceptance tests in the purchase agreement. |
| Rack and Facility Compatibility | Standard data-center racks commonly use 19-inch equipment width and rack units of 1.75 inches per U; GPU servers may occupy several U. | Confirms rack depth, rail loading, cable clearance, power connectors, airflow direction, and facility cooling requirements before production. | Compare the mechanical drawing with the target rack, power distribution units, aisle design, floor loading, and cooling capacity. |
| International Compliance and Documentation | International shipments may require market-specific safety, electromagnetic-compatibility, environmental, and import documentation. | Supplies accurate technical files, product labels, packing lists, certificates where applicable, and destination-specific shipping support. | Verify documentation with the destination country’s importer, customs broker, safety authority, and IT procurement requirements. |
| Warranty and Global Support | GPU server downtime can affect model training, hosted services, and production workloads; response procedures are therefore part of system value. | Defines warranty scope, remote diagnosis, spare-parts availability, escalation routes, repair turnaround, and cross-border return responsibilities. | Request a written service-level agreement, spare-parts list, RMA workflow, support hours, and remote-management access policy. |
| Transparent Total Cost | The purchase price is only one component; freight, duties, installation, support, power, cooling, and replacement parts affect total cost of ownership. | Provides an itemized quotation with configuration assumptions, delivery terms, taxes or duties responsibility, warranty costs, and upgrade pricing. | Compare equivalent configurations using the same GPU count, memory, storage, networking, delivery terms, and support period. |
Reference basis: PCI-SIG PCI Express specifications, common 19-inch rack conventions, data-center hardware engineering practice, and destination-market compliance requirements. Actual performance and power values vary by selected components, firmware, workload, and operating conditions.
Start with the workload, not a hardware list. Define model size, batch volume, latency targets, and operating hours. Training may need several GPUs and fast interconnects. Inference may need fewer GPUs and a stronger CPU balance. There is no universal setup.
A dense server can exceed 6 kilowatts in one rack position. Check circuits, voltage, rack capacity, and energy costs before ordering. Cooling also matters. A warm server room can expose design weaknesses quickly.
Air cooling can suit moderate workloads with manageable heat output. Liquid-assisted cooling may support higher density. However, local facilities must support it. Confirm plumbing, maintenance access, and service procedures. Cooling plans are easy to underestimate.
High-throughput training requires fast interconnects and carefully selected switches. Remote inference may prioritize stable bandwidth and secure management paths. Network choices affect training time and response consistency. Faster is not always better if the design is unbalanced.
Match storage performance to data movement. Do not choose capacity alone. Large datasets may need faster reads and writes. Confirm storage interfaces, usable capacity, and expected workload patterns. Paper specifications can mislead.
Share GPU quantity, memory, storage, network speed, rack size, and local power standards. Include environmental conditions when possible. The written specification should list components, testing steps, warranty terms, and production timing. Small connector differences can delay installation.
Request burn-in testing, temperature checks, and serial-number verification before packing. Anti-static materials, shock protection, and moisture control help during transport. Ask for packing photos and tracking updates. Delivery dates can shift because of weather or customs reviews.
Support should cover rack placement, firmware checks, network setup, and GPU monitoring. If a fault appears, provide logs, error codes, and clear photos. Ask about spare parts, response times, remote diagnosis, and replacement procedures. Promises may sound complete but remain vague. Ask again.
Choosing a top China custom gpu server builder requires more than comparing prices or advertised specifications. A reliable manufacturer should demonstrate strong engineering expertise, flexible configuration capabilities, and a clear understanding of global workloads such as artificial intelligence, machine learning, scientific computing, rendering, and data analysis. Server designs should balance GPU performance, CPU compatibility, memory capacity, storage speed, networking, cooling, power efficiency, and future expansion needs.
Global buyers should also evaluate manufacturing standards, component traceability, testing procedures, quality control, warranty terms, and international compliance documentation. A dependable supplier can support chassis customization, rack integration, firmware configuration, operating system installation, and workload-based optimization while maintaining consistent production quality. Clear communication about quotations, lead times, packaging, shipping arrangements, customs documentation, and technical support is equally important. From initial consultation to installation and after-sales service, the best partner provides transparent processes, responsive assistance, and practical solutions that help customers deploy reliable GPU infrastructure with confidence.